ResearchForge
ResearchForge: AI research paper assistant
Full-stack AI research assistant engineered with schema validation to decline unsupported queries rather than hallucinate.
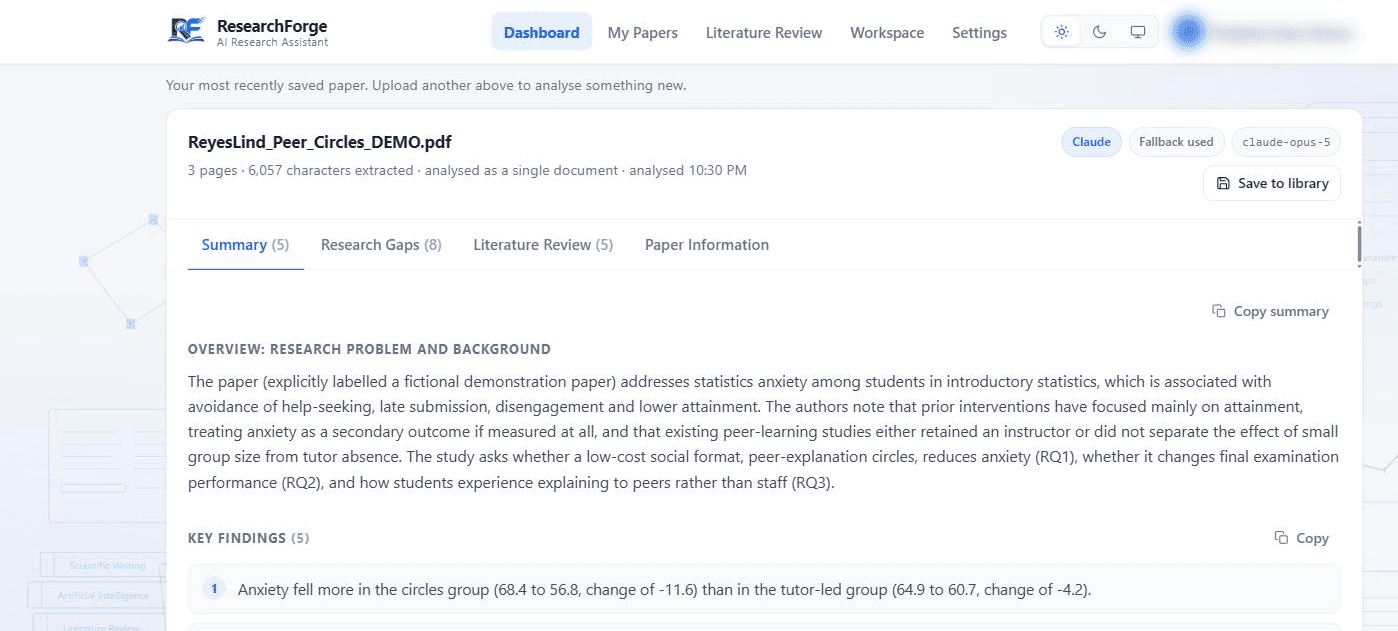
A university AI research-paper assistant, live on its own domain. Upload a paper and get a summary, a gap analysis carrying its own evidence, and a literature review, with the system declining rather than inventing where the paper does not support a section. Built end to end: planning documents through architecture, Next.js and FastAPI, PostgreSQL Row Level Security, 538 tests, deployment and maintenance.
End-to-End Planning, Dual-Service Architecture, AI Pipeline & Automated Tests
Key Highlights & Practical Impact
Executive Scan- Architected dual-service system on Vercel: FastAPI Python backend paired with Next.js frontend behind a single origin
- Enforced 4-layer groundedness: explicit model decline paths, strict schema validation, and immediate discard of invalid outputs
- Designed provider abstraction with automatic failover: Groq (qwen3.6-27b) primary with Anthropic (claude-opus-5) fallback
- Implemented database-level data isolation via PostgreSQL Row Level Security (RLS) ensuring strict per-user boundaries
- Engineered 538 automated tests (522 backend with pytest, 16 frontend with Vitest) running offline without API consumption
Ready to explore the build?
A detailed look at the end-to-end architecture, process workflows, key engineering decisions, live production capabilities, challenges, and results.
Writing from this work
The Wrong Supabase Key Doesn't Fail. It Returns 200 and Zero Rows.
A publishable Supabase key in a server slot meant for a secret one: every read succeeded with no rows, the dashboard showed confident zeros, and the health check said all was well.
The Plan Said RAG. The Papers Said Send the Whole Thing.
ResearchForge was planned as a retrieval pipeline. Measured papers fit whole in the context window, so it sends the full text and only chunks a genuinely oversized document.
Vercel or a Self-Hosted Ubuntu Box? How I Chose Hosting App by App
Eight deployed apps, three hosting shapes: Vercel for pages and serverless APIs, a self-hosted Ubuntu box for a stateful API, and a hybrid for a model Vercel can't run.
Two Ways I Use Supabase Row Level Security: Deny-All Behind a Server, or Per-Owner Policies
Across five projects, RLS does one of two jobs: close the Data API while a trusted server does the work, or let Postgres enforce who owns each row. When to pick which.
Testing Without Paid APIs or Hardware, and the Places Fakes Lied
Fake LLM providers, a simulated label printer and an in-process Postgres keep my test suites free and offline. What each proved, and three places a fake fell short.
Testing an LLM App Without Calling a Paid API
538 tests for an LLM application, none of which call a paid model. FastAPI dependency overrides, a fake provider, generated PDFs, opt-in live tests, and where fakes stop telling the truth.
Why Supabase Google Sign-In Landed on localhost With a Token in the URL
Google sign-in on a custom domain returned users to localhost:3000 with an access token in the address bar. Two separate causes, the Site URL fallback and the implicit flow, and the fixes.
When the Code Ships Before the Migration: Degrading One Schema Level at a Time
Selecting a column that a pending migration adds made PostgREST fail every library read. The fix degrades one migration tier at a time, so deploy order stops mattering.
Planning a University Project Like a Real One: Milestones, Risks and a Decision Log
The first commit of ResearchForge had no code: a plan with milestones, a risk register, a definition of done and numbered decisions. What that structure caught, and where the plan was wrong.
One Pydantic Schema, Two LLM Vendors: Native Parsing vs JSON Mode
The same Pydantic models drive structured output from Anthropic's native parsing and Groq's JSON mode. Forbidding extra fields, catching truncation, and validating instead of repairing.
One Checked Value Instead of Two Booleans: Making a Bad Config Unrepresentable
Two on/off flags allow a state with no correct behaviour: both off. Storing the enabled set as one CHECK-constrained value and validating the resulting state instead.
Logout Still Worked for 30 Seconds: Token Caches on Serverless
A token verification cache meant a signed-out session kept working for up to 30 seconds. Why evicting on sign-out does not fix it on serverless, and why the answer was a small measured bound.
The Retries You Didn't Write: LLM Rate Limits and SDK Hidden Retries
A client library's default retries turned one rate-limited analysis into twelve requests against a free tier of twenty. Removing requests, telling limits apart, and returning 429 with Retry-After.
A Cross-Paper Literature Review Built From Stored Analyses, Not PDFs
Building one LLM literature review across several saved papers by reading their stored analyses instead of re-sending every PDF. The trade-off, the size guards, and why partial results are refused.
When a Per-Minute Token Limit Is Smaller Than One Request
A free-tier limit of 7,000 input tokens per minute, and research papers needing 7,920 to 20,362 tokens per call. Why waiting cannot fix that, and how a working fallback hid it.
Getting Usable Text Out of Academic PDFs: Signatures, Encryption, Scans and Ligatures
The PDF ingestion path behind ResearchForge: checking the real file signature, opening print-restricted files, rejecting scans with no text layer, and cleaning text without removing content.
Evaluating an LLM App When Your Own System Hides the Result
Evaluating a deployed LLM app with no labelled data, and the three things that produced plausible but wrong measurements: a content-keyed cache, a CDN and a fallback that worked too well.
Choosing an Embedding Model Under pgvector's 2,000-Dimension Index Limit
A decision record: how ResearchForge picked an embedding model and dimension around pgvector's index limit, cost and reversibility. The choice was made and wired up; no embedding was ever produced.
Calling Supabase's PostgREST Directly From FastAPI: The Details a Mock Won't Tell You
A Python backend talking to Supabase's PostgREST over plain httpx. Embedded ordering, counts in headers, deletes that return 200, reserved characters, and what mock tests can and cannot prove.
Caching LLM Analyses by Content Hash Without Recording Who Uploaded What
A shared cache for expensive LLM analyses, keyed by a hash of the extracted text. How the key is chosen, what is never cached, and why the cache table has no user column.
Running FastAPI and Next.js as Two Services Behind One Vercel Origin
One Vercel project, a Next.js frontend and a FastAPI backend on the same origin. The routing, the CORS outage it fixed, the image optimizer that vanished, and the Python packaging details.
Building Software in Cyberjaya: The Development Environment Behind the Work
What a production operations system, a client website, an AI research assistant and a vision inspector actually get built on, from a laptop in Cyberjaya: the machine, the stack, where things are hosted, and the local details that shaped the code.
A Vision Model That Only Observes: Building RPOMS AI Without Letting the Model Decide
A router surface inspector where the vision model reports what it sees and a deterministic rule engine decides. Why the split, what a 7B open model actually scored, the blank-image control that changed the prompt, and a safety gate that turns most answers into "check manually".
Every Policy Was Correct, and Every Policy Was Inert
A data-isolation defect that passed the entire test suite, shipped, and behaved perfectly. What it took to find it, and why the fix was to stop asking the application to be careful.
When Not to Fall Back to Another AI Provider
Automatic failover between model vendors is easy to build and easy to build wrong. Most errors should never trigger it.
Making an LLM Admit the Paper Doesn't Say That
The dangerous failure of an AI summarising tool is not a blank answer. It is a plausible one about a section that was never in the source. Enforcing groundedness in four layers instead of asking for it once.